
// Starter
For prototypes and light workloads.
$39
30,000 Plan Credits
Fetch, render, crawl, and extract web data for AI agents with one API your team can reason about.
$ curl -X POST "$SPIDER_BASE_URL/v1/fetch" \
  -H "Authorization: Bearer $SPIDER_API_KEY" \
  -H "Content-Type: application/json" \
-d '{"url":"https://www.wikipedia.org/"}'Until external claims are verified, the website points to concrete API surfaces and documentation.
SpideyData gives products a single path from fast fetches to browser-backed pages and multi-page jobs.
Start with the fast path for pages that can be read without a browser.
Use managed browser rendering when a page needs JavaScript before content is usable.
Run multi-page jobs when an agent needs more than one URL.
Turn page content into structured fields your product can use.
The homepage proves the API quickly. Platform and docs pages can carry denser examples for developers.
$ curl -X POST "$SPIDER_BASE_URL/v1/browser/scrape" \
  -H "Authorization: Bearer $SPIDER_API_KEY" \
  -H "Content-Type: application/json" \
-d '{"url":"https://www.wikipedia.org/","browser":{"wait_for_selector":"body"}}'Use SpideyData where agents, pipelines, monitors, and product surfaces need explainable web inputs.
Give agents a dependable way to read the web without owning browser infrastructure.
Collect source pages for retrieval, enrichment, and review workflows.
Track pages that matter to your product and explain how each run completed.
Add web data to internal tools, research flows, and customer-facing automations.
Route users from the website into copyable examples, public API reference, and the product console.
$ curl -X POST "$SPIDER_BASE_URL/v1/browser/scrape" \
  -H "Authorization: Bearer $SPIDER_API_KEY" \
  -H "Content-Type: application/json" \
-d '{"url":"https://www.wikipedia.org/","browser":{"wait_for_selector":"body"}}'Field-tested patterns for choosing fetch, browser, crawl, and extraction paths.
Browse all articles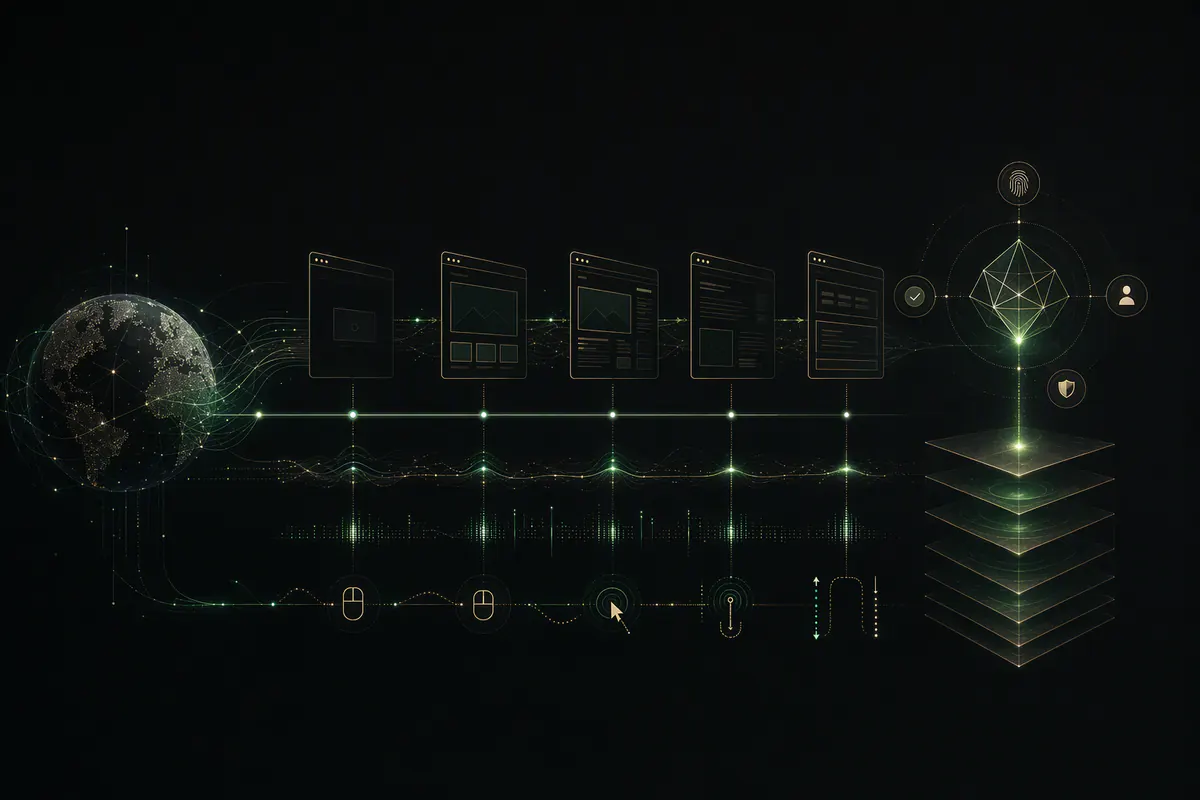
Modern defenses correlate network identity, navigation, interaction, resource timing, and session history instead of trusting one browser fingerprint.
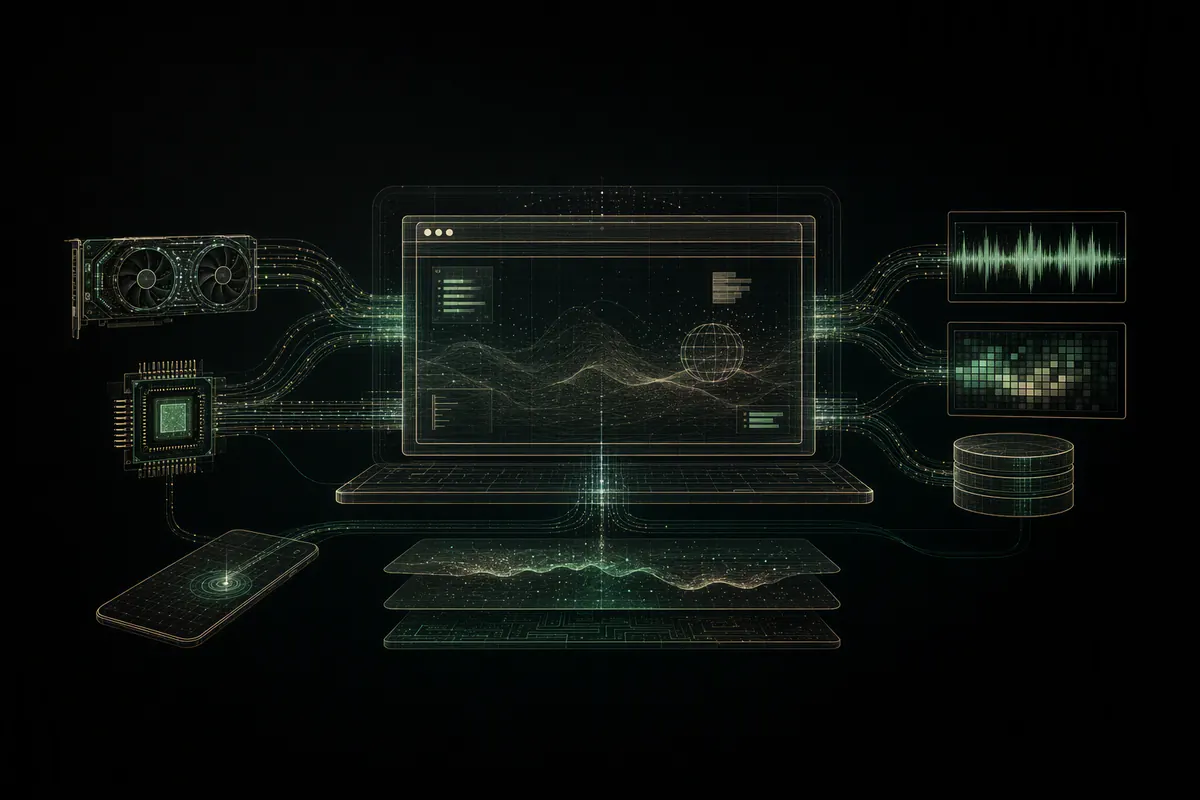
Canvas, WebGL, audio, clean realms, WebAssembly, storage, and automation traces become meaningful when they are evaluated as one device story.
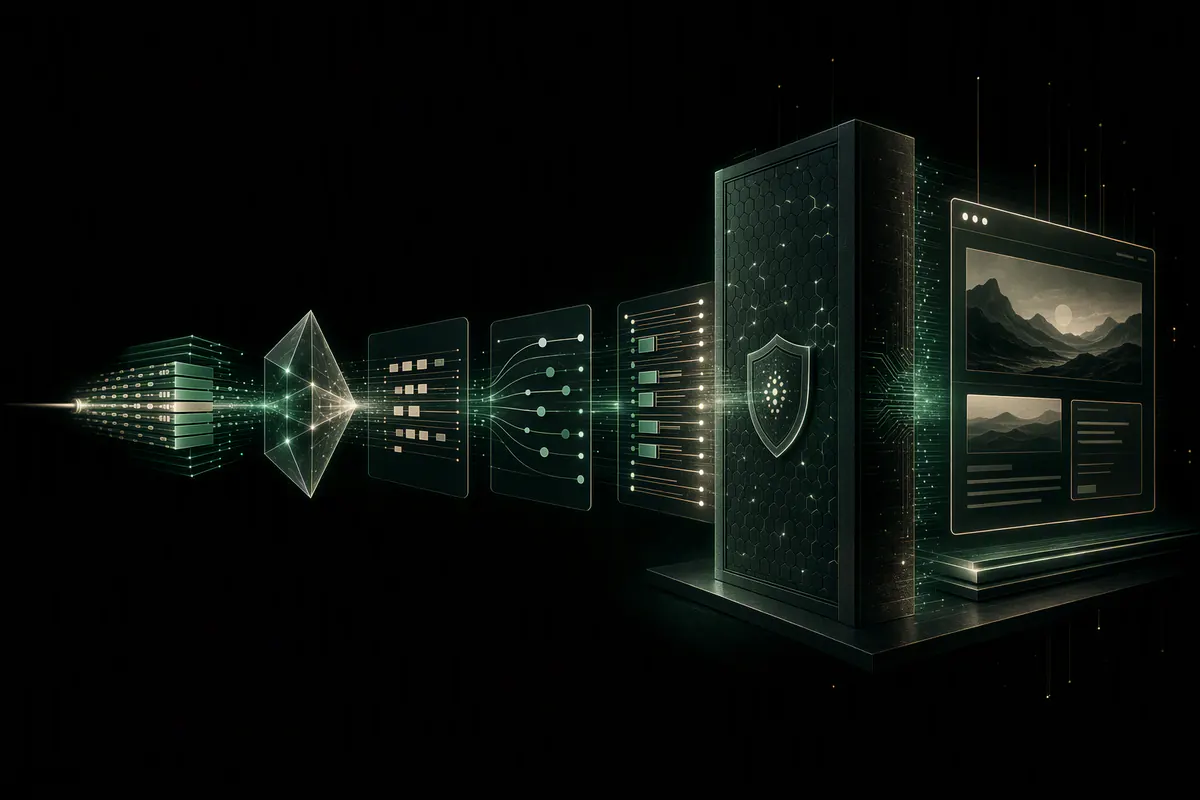
TCP, TLS, HTTP/2, headers, and QUIC each reveal part of a client implementation—and contradictions across layers are stronger than any one fingerprint.
For prototypes and light workloads.
For growing teams and higher volume.
For advanced needs and custom scale.
Custom price and Plan Credits are confirmed before any order.
Plan Credits are used first. Credits balance never expires.